LoRA (Low-Rank Adaptation) fine-tuning updates a model by learning low-rank matrices that approximate weight changes, while the base model weights remain frozen. It achieves competitive task adaptation with far fewer trainable parameters than full fine-tuning, making customization cheaper and faster.
When to use LoRA
Use LoRA when you want to:
- Adapt a large pre-trained model to a specific task (classification, extraction, summarization, instructions) with limited compute
- Maintain the base model’s general capabilities while adding new behaviors (tone, format, domain terminology)
- Ship multiple variants (per customer, product line, or region) by deploying small adapters instead of multiple full model copies
- Iterate quickly with frequent retraining (weekly/daily) on new data
- Fine-tune with datasets that are small to medium (often thousands to low hundreds of thousands of examples)
When not to use LoRA
Avoid (or be cautious with) LoRA when:
- You need deep capability changes that may require updating many layers/weights (some complex reasoning or heavy math/code gains can be harder)
- Your task requires large-scale continued pre-training (LoRA is not a substitute for pre-training)
- You need maximum accuracy and have budget for full fine-tuning and rigorous evaluation at scale
- Your constraints are dominated by inference latency from model size (LoRA reduces training cost more than it reduces runtime)
- You cannot control dataset quality (LoRA can efficiently amplify bad labels, bias, or unsafe examples)
Signals you need LoRA
You likely need LoRA if:
- Full fine-tuning is blocked by GPU memory limits or costs
- You want to customize behavior without risking catastrophic forgetting
- You need many specialized variants but can’t store or manage multiple full checkpoints
- Your experiments stall because training cycles take days/weeks, and you need hours/days
- Your “prompt-only” approach has plateaued and you need more consistent outputs than prompting can provide
The New Era of Model Customization
AI models traditionally require resource-intensive fine-tuning to meet specific business needs, creating barriers for many developers and organizations due to prohibitive costs and long development cycles.
Key Challenge: Adapting billion-parameter models efficientlyTraditional Problem: High computational costs + lengthy developmentHowever, new efficient adaptation techniques are democratizing AI access. LoRA Fine-Tuning (Low-Rank Adaptation) emerges as a leading solution, enabling developers to specialize pre-trained models for narrow tasks—like fitting specific attachments to general-purpose tools.
LoRA maximizes performance while minimizing computational overhead and memory footprint. This paradigm shift allows developers to create highly performant, custom models without massive investments traditionally required for full fine-tuning, unlocking new levels of agility in AI development.
Understanding the Foundation: Pre-training vs. Fine-tuning
Before diving into LoRA, it’s essential to understand the distinction between pre-training and fine-tuning. Pre-training is the foundational process of building a model from scratch. This involves feeding a model with a massive, diverse dataset and allowing it to learn all of its parameters from the ground up. This is a monumental task, demanding immense computational resources and a vast quantity of data.
Fine-tuning is a more targeted approach. It starts with a pre-trained model that already possesses a broad understanding of a subject. A developer then makes slight adjustments to the model’s parameters to refine it for a specific, downstream task. This process requires significantly less data and computational power than pre-training a model from scratch. However, even traditional fine-tuning can be expensive and time-consuming, as it still requires modifying the entire set of parameters.
How LoRA Fine-Tuning Works
At its core, Low-Rank Adaptation (LoRA) is a technique for quickly adapting machine learning models to new contexts without retraining the entire model. The method works by adding small, changeable parts to the original model, rather than altering the entire structure. This approach helps developers expand the use cases for their models in a much faster and more resource-efficient way.
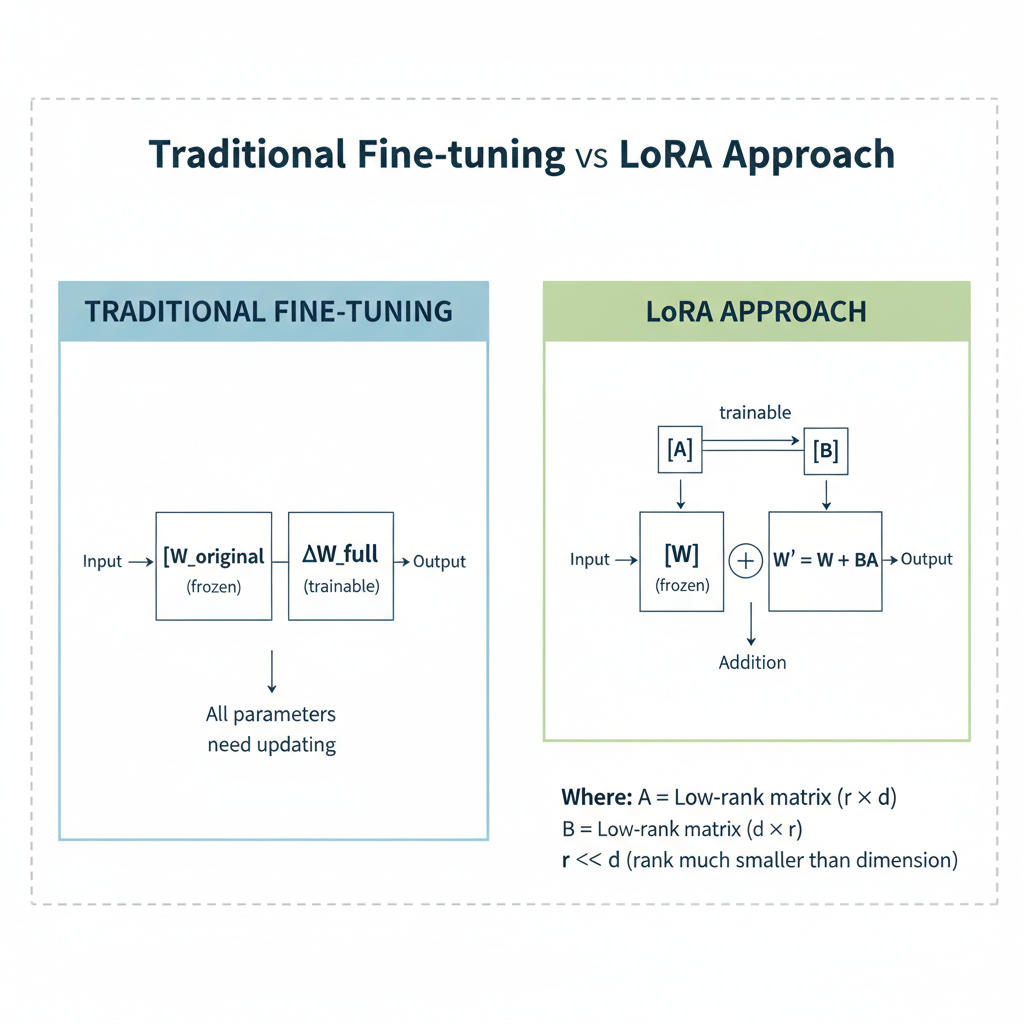
The technical genius of LoRA lies in its use of “low-rank matrices”. In traditional fine-tuning, the goal is to change the original weight matrix (W) of a neural network to fit a new task. The change itself is represented by a separate matrix, ΔW. LoRA introduces a clever shortcut: instead of trying to calculate and apply the full, complex
ΔW matrix, it breaks it down into two much smaller, lower-rank matrices, A and B. The updated weight matrix becomes W′=W+B·A, where the original weight matrix (W) is kept “frozen” and unchanged.
Traditional: W' = W + ΔWLoRA:       W' = W + B·A
Where:- W  = Original weight matrix (frozen)- ΔW = Full parameter update matrix- A  = Low-rank matrix (trainable)- B  = Low-rank matrix (trainable)- B·A = Low-rank approximation of ΔW
This decomposition is crucial for reducing the computational overhead. The number of trainable parameters is dramatically reduced because the small matrices A and B have far fewer values than the original weight matrix. For example, a large weight matrix might have billions of parameters, but with LoRA, the trainable parameters for a model like GPT-3 can be reduced from 175 billion to around 18 million. This results in significant savings in GPU memory and processing power, making it a highly cost-effective solution for adapting large models.
Parameter Reduction Comparison
| Model Component | Traditional Fine-tuning | LoRA Fine-tuning |
|---|---|---|
| GPT-3 Parameters | 175 billion | ~18 million |
| Reduction Factor | 1× (baseline) | ~9,700× smaller |
| Memory Usage | High | Significantly reduced |
| Training Speed | Slow | Fast |
| Cost | High | Low |
The Advantages of LoRA over Full Fine-Tuning
LoRA provides several key benefits that make it a compelling alternative to full fine-tuning.
Practical Comparison
| Stage | GPT Example | Required Resources | Time |
|---|---|---|---|
| Pre-training | Train GPT from scratch | 1000+ GPUs, $10M+ | Months |
| Full Fine-tuning | Specialize for medicine | 10-50 GPUs | Days/weeks |
| LoRA | Add Python knowledge | 1-4 GPUs | Hours/days |
Key Benefits:
• Parameter Efficiency: Dramatically reduces trainable parameters. QLoRA variant uses 4-bit/8-bit quantization for single 24GB GPU compatibility
• Prevents Catastrophic Forgetting: Freezes original parameters, preserving pre-trained knowledge
• Comparable Performance: Matches or exceeds full fine-tuning results. Built-in regularization prevents overfitting on small datasets
• Resource Savings: Less memory usage + faster training times
When to Choose:
- Full Fine-tuning: Complex domains (programming, mathematics) where accuracy is paramount
- LoRA: Most instruction fine-tuning scenarios with smaller datasets - more efficient and equally effective
LoRA offers compelling resource efficiency without sacrificing performance for most use cases.
A Deeper Dive into Implementation and Best Practices
Implementing LoRA involves a structured process, and several frameworks and tools have emerged to simplify the workflow. One popular example is the AI Toolkit for Visual Studio Code, which provides a straightforward way to create a LoRA adapter for models like Microsoft’s Phi Silica. Developers can define the model and provide high-quality training data in JSON files to generate a custom adapter.
When implementing LoRA, several best practices can maximize performance and model quality.
Data Quality is King: The effectiveness of a LoRA adapter is highly dependent on the quality and quantity of the training data. It is recommended to use thousands of diverse, high-quality examples to achieve the best results.
Hyperparameter Tuning: Like any machine learning process, optimizing hyperparameters is critical. The learning rate, in particular, is highly sensitive for LoRA, and finding the optimal value through experimentation is essential for stable and effective training.
Continuous Evaluation: It’s crucial to track and evaluate the performance of different fine-tuning methods. Experiment tracking ensures reproducibility, allows for collaboration, and helps identify the best training configurations.
LoRA in Action: Real-World Use Cases
The efficiency of LoRA fine-tuning makes it a perfect fit for a wide range of applications.
Domain-Specific LLMs: Companies can use LoRA to take a general-purpose LLM and adapt it to a specific industry, such as finance or healthcare, to understand specialized terminology and provide more accurate responses. This allows for the creation of powerful, custom-tailored virtual assistants.
Improved Visual Models: Beyond text, LoRA can be applied to text-to-image diffusion models. Developers can use a scaling factor to control how much the model is fine-tuned for a particular style or output.
Edge Computing and IoT: The lightweight nature of LoRA adapters makes them ideal for running on devices with limited computational resources, like smartphones or IoT devices. This is crucial for applications where low latency is a requirement and sending data to a remote cloud is not feasible.
Common mistakes (and fixes)
- Using low-quality or inconsistent training data Fix: standardize schemas, remove contradictions, deduplicate, and add hard negatives.
- Overfitting small datasets (model becomes brittle) Fix: add diversity, use validation early stopping, tune rank and dropout, and evaluate out-of-domain.
- Choosing rank arbitrarily Fix: start small (e.g., low rank), then increase only if evals plateau; treat rank as a budget knob.
- Not testing regressions against the base model Fix: keep a “base capability” test suite; require no unacceptable regressions before shipping.
- Confusing “style adaptation” with “knowledge injection” Fix: for factual updates, consider retrieval (RAG) or updated training corpora; LoRA helps behavior but doesn’t guarantee reliable new facts.
Limitations
- LoRA primarily improves training efficiency, not necessarily inference speed
- Adapter performance depends heavily on dataset quality and representativeness
- Not ideal for replacing retrieval when you need fresh, source-grounded facts
- Requires careful evaluation to avoid bias amplification and unsafe behaviors
Mini FAQ
“What is LoRA fine-tuning in simple terms?” LoRA fine-tuning customizes a model by training small adapter matrices that approximate weight updates, while keeping the original model unchanged.
“Is LoRA as good as full fine-tuning?” Often yes for many instruction and domain adaptation tasks, but full fine-tuning can win when you need maximum accuracy and have enough compute and data.
“Does LoRA reduce inference latency?” Usually not significantly. It mainly reduces training cost and checkpoint size; latency is still driven largely by the base model size and hardware.
“How much data do I need for LoRA?” It varies, but high-quality thousands of examples can work for narrow behaviors; broader or more complex tasks need more data and stronger evaluation.
“Should I use LoRA or RAG?” Use LoRA to change behavior/style/format reliability; use RAG to supply up-to-date or verifiable knowledge at runtime. Many production systems use both.
Conclusion: The Future of Efficient AI Adaptation
The introduction of LoRA fine-tuning marks a pivotal moment in AI development, democratizing access to the customization of large, complex models. By freezing the vast majority of a model’s parameters and adding small, trainable low-rank matrices, LoRA solves the problem of excessive resource consumption, making fine-tuning a practical reality for a broader audience. This approach not only saves time and cost but also helps mitigate the risk of catastrophic forgetting, ensuring that the valuable knowledge of pre-trained models is preserved.
The rise of parameter-efficient fine-tuning (PEFT) techniques, with LoRA at the forefront, is reshaping how we build and deploy AI. The future of AI innovation is not just about creating larger and larger models but about making them more adaptable, accessible, and efficient.
Build AI-powered applications by running AI models on Azion’s highly distributed infrastructure to deliver scalable, low-latency, and cost-effective inference — it is a strategic necessity for developers looking to create high-performing, custom AI solutions in a fast-paced, resource-conscious world.